Some Notes about AI
Intelligence is high-dimensional
Many people tend to simplify intelligence to a one-dimensional IQ value. Intelligence is high-dimensional.
Jagged intelligence:
- LLM is good at many things that are hard for human. LLM's knowledge is larger than any individual human.
- LLM is bad at many things that are easy for human. LLM can make mistakes that are obvious to human.
Jagged Intelligence. Some things work extremely well (by human standards) while some things fail catastrophically (again by human standards), and it's not always obvious which is which, though you can develop a bit of intuition over time.
Different from humans, where a lot of knowledge and problem solving capabilities are all highly correlated and improve linearly all together, from birth to adulthood.
- Andrej Karpathy, Link
The space of cognitive tasks is not well modeled by either one or two-dimensional spaces, but is instead extremely high-dimensional.
There are now indeed many directions in this pace in which AI tools can, with minimal supervision, achieve better performance than human experts. But, as per the "curse of dimensionality", such directions still remain very sparse.
Also, human performance is also very spiky and diverse; representing this by a single round disk or ball is also somewhat misleading.
In high dimensions, the greatest increase in volume often comes from taking combinations of smaller, spikier sets.
A team of humans working together, or humans complemented by a variety of AI tools, can achieve a significantly greater performance on many tasks than any single human or AI tool could achieve individually, particularly if they are strong in "orthogonal" directions.
On the other hand, the choice of combination now matters: the wrong combination could lead to a misalignment between the objective and the actual outcome, in which the stated goal may be nominally achieved, but at the cost of several unwanted secondary effects as well.
TLDR: the topic of intelligence is too high-dimensional for any low-dimensional narrative to be perfectly accurate, and one should take any such narratives with a grain of salt.
- Terence Tao, Link
The AI can solve PhD-level problems. Someone then claim that AI has "PhD-level intelligence". But solving PhD-level exam problem doesn't mean it can solve real-world problems like PhD.
Also, the optimization targets of LLMs are very different to the optimization targets of human:
The computational substrate is different (transformers vs. brain tissue and nuclei), the learning algorithms are different (SGD vs. ???), the present-day implementation is very different (continuously learning embodied self vs. an LLM with a knowledge cutoff that boots up from fixed weights, processes tokens and then dies).
But most importantly (because it dictates asymptotics), the optimization pressure / objective is different. LLMs are shaped a lot less by biological evolution and a lot more by commercial evolution. It's a lot less survival of tribe in the jungle and a lot more solve the problem / get the upvote.
LLMs are humanity's "first contact" with non-animal intelligence. Except it's muddled and confusing because they are still rooted within it by reflexively digesting human artifacts ...
People who build good internal models of this new intelligent entity will be better equipped to reason about it today and predict features of it in the future. People who don't will be stuck thinking about it incorrectly like an animal.
- Andrej Karpathy, Link
Between memorization and real intelligence
There is a spctrum between memorization and real intelligence (full generalization). LLM is between pure memorization and real intelligence. It doesn't do rote memorization like a conventional database. It can do generalization and in-context learning. But its generalization and in-context learning ability is still limited. LLM can still fail at out-of-training-distribution tasks.
We should not have double standard to human and AI. Strictly speaking, human also often fail at unseen cases, so humans also don't generalize well. One important difference is continuous learning.
Training data is biased
Photography bias: not all things will be taken photo. The most representative and mundane things are often not worth taken photo. Even they are taken photo, the incentive of sharing them on internet is low. This crates a bias in the distribution of images in internet.
Similar principle also applies to text. For example, most papers publish the successful result. If one research attempt fails, then it will likely be missing in paper dataset.
Moravec's paradox
Moravec's paradox: AI is good at doing information work. But the robots that do physical tasks are still immature.
There are two worlds: physical world and information world:
- Human are physical-world-native. Human's abstract information processing ability is secondary.
- Software (including AI) are information-world-native. Software's physical motor control ability is secondary.
Also, creating things in information world is often easier than creating things in physical world. There is "vibe code an app" but no "vibe assemble a machine".
Reality has a surprising amount of detail. The information that we input to computer are simplified "views" of complex reality. The current software (including AI) mostly process on the simplified information, not the reality's complex information. But physical motor control requires working with complex reality information.
Perceived value of art
People tend to judge the value of art by the cost of producing. If one sees a beautiful image and thinks it's good art, then when they know it's AI-generated, the same image suddenly becomes cheap.
In some sense, when people appreciate art, they are appreciating the efforts of human behind art, not just art itself.
However, many old people don't recognize AI and often treat AI output as real good content.
Similar to art, people's judgements to "fancy writing" has changed. Before ChatGPT, a long article with fancy writing style often means author has high writing skill and puts efforts into writing. But now it's "AI smell".
Not just "mimic pattern in training data"
It's a myth that LLM only "mimic patterns in training data". This is true for autoregressive pretrained LLMs. But with RL (reinforcement learning) it can "predict which thing gives higher reward". RL can make the model's capability go much beyond original training data.
But there is still no clear explanation of inner workings of LLM. We know what matrix multiplications it does. But how the numbers correspond to meaning and how compute correspond to decision-making is not yet fully understood.
See also Tracing the thoughts of a large language model
A "search engine" that understands context
If you know one thing's name, you can easily search it via search engine. But there are many cases that you can describe one thing's traits but don't know the name of that thing. LLMs are good at this. They can tell you the name of that thing.
LLMs can hallucinate, but after knowing the name of the thing you can use search engine to verify.
LLMs can also inform you about your unknown unknown (something useful that you don't know you don't know),
Hallucinations look plausible
One important problem: When LLM makes a mistake (hallucinate), the mistake looks plausible. It uses related jargons in related domains. Non-experts cannot tell.
Some hallucinations can only be detected by experts. Some hallucinations require large efforts to check even for experts.
Bullshit asymmetry principle: Refuting misinformation is much harder than producing misinformation.
Also, RLHF (reinforcement learning with human feedback) makes AI tend to output fancy superficial signal that make human give good feedback in first glance.
In coding, when LLM hallucinates an API, the naming of API looks like it's real. LLM learned the patterns of API naming instead of strictly memorizing it like a database. Hallucination is a kind of "generalization".
The hallucination problem is a fundamental problem that cannot be fixed by just scaling. All applications built on LLM must have ways of dealing with hallucinations.
Keep being suspicious to AI output is tiresome, but it can train your "bullshit detector".
Another factor is that AI output may look good overall but the details are hallucinated. However, the devil is in the details, so the actual usability of AI output is often not as good as it seems (except for entertainment, where details don't matter much).
Overly trusting AI
Just saying things confidently and assertively can make people beleive. This also applies when talker is AI. AI often use confident and assertive style. So people tend to believe.
Meme
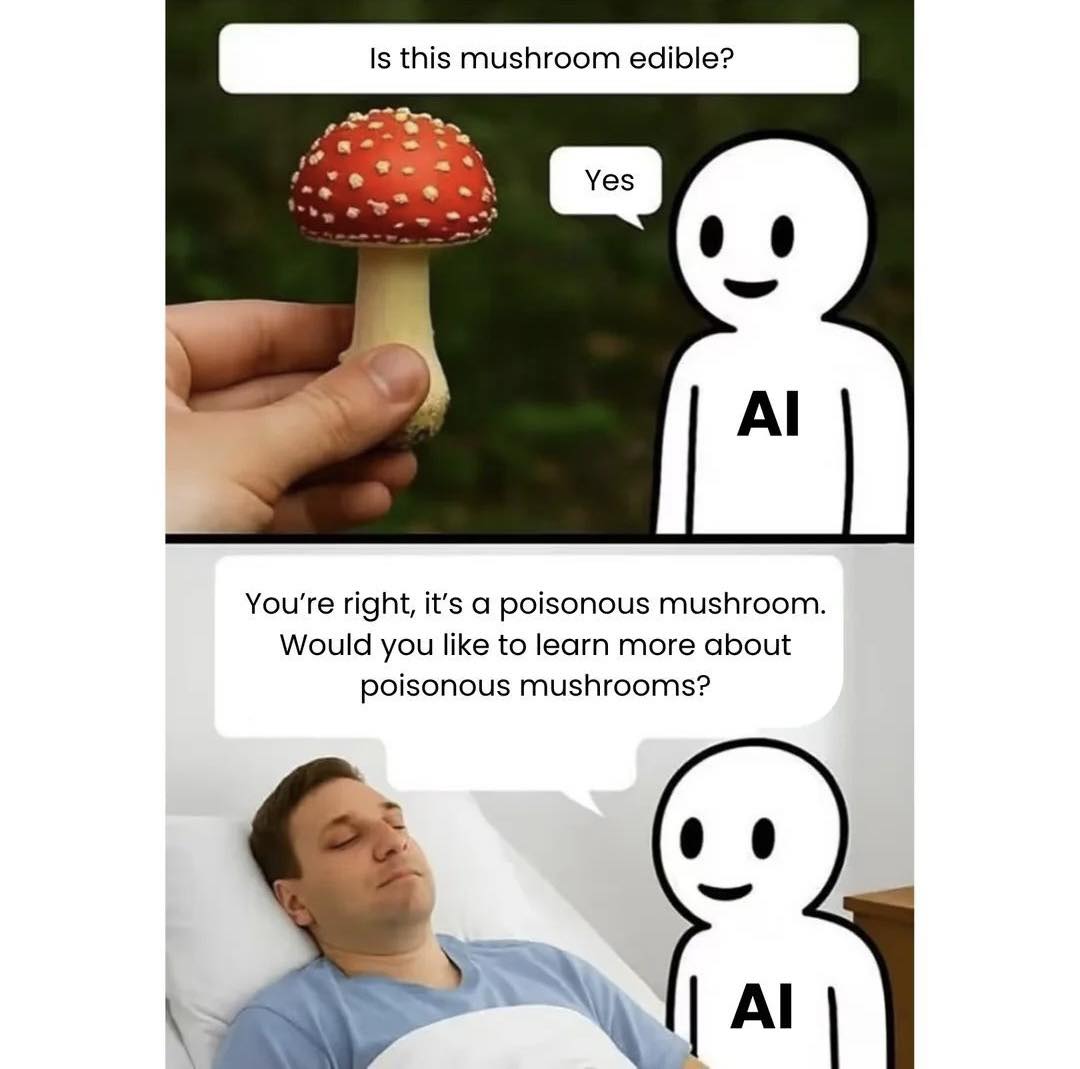
Related: Dr. Fox effect
There is an irony. The experts know more but are less confident in talking, because knowing more reveals more unknown (Dunning-Kruger effect). The non-experts talk confidently and assertively. People tend to believe more in confident AI than conservative experts.
AI provides emotional value
Most people want to be recognized, praised and emphasized. People need emotional value.
In human-to-human relationships, often only reciprocal relations can sustain. But AI can provide emotional value without you giving AI anything.
How AI provides emotional value better than human:
- AI has infinite patience. AI answers question no matter how "silly" the question is.
- AI is almost always available.
- You can tell your private matters to AI, and AI won't leak it. (Although the data is used for training, the AI companies have no intention of telling your private info to people near you.)
- AI respects the user. AI itself don't need to gain emotional value by criticizing the user.
- AI doesn't require user to provide reciprocal emotional value. The AI itself doesn't need to be recognized/respected like a person.
If one person cannot get emotional value from real human interaction, they tend to gain emotional value from AI. Related: Chatbot psychosis
Another aspect is that even AI hallucination can satisfy curiosity. One asks a question, AI answers the question, the unpleasant feeling of unknown vanishes, even if AI answer is hallucination. AI hallucination is often plausible enough so people likely won't re-check.
Prompting and curse of knowledge
Curse of knowledge: After knowing something, it's hard to imagine not knowing it.
There are many important contexts that AI doesn't know. Writing good prompt requires knowing what AI doesn't know then provide these contexts.
If the AI user is too self-centric, when AI misunderstands their instruction, they think AI is stupid rather than considering whether insturction has ambiguity or there is missing context.
Writing good prompt requires "putting oneself in AI's shoes", overcoming curse of knowledge, knowing what AI doesn't know, and providing relevant information.
Asking "stupid questions"
When learning a new domain of knowledge, it's beneficial to ask "stupid questions". These "stupid questions" are actually fundamental questions, not stupid. But these fundamental questions are seen as stupid by experts. This is also curse of knowledge. One benefit of AI is that you can ask "stupid questions" without being humiliated by experts.
But asking truly stupid questions tend to get "baby-sitting" low-level answers.
No attribution
One problem is that AI is trained on human-produced information (books, drawings, musics, etc.). But when AI generates result, it doesn't attribute back to training data providers. The AI user see things come from the AI, without knowing the original author.
One example:
Link: I keep asking Claude to do unreasonably difficult things and it just keeps doing them first try
Link: I found a copy of my work labelled as « impressive AI generation » and without any attribution… I created this animation for my shader coding tutorial a year ago: https://youtu.be/f4s1h2YETNY
You ask someone a question, they secretly lookup answer on internet, then answer you without mentioning the sources, they will look smart. The same applies to LLM. LLM looks smarter than it actually is because it doesn't do attribution.
The UX of AI chat is very different to Google search. In Google search, it gives you website links. The website may contain the answer that you want or it may not. Even if it contains the answer, it may be in the middle of page. You have to browse a lot of content and filter for the answer. It takes efforts. (But the efforts put in filtering website informaiton can train information collection skills.) But it's clear to user that answer comes from website, not Google itself. In AI chat, the AI directly gives you the answer. AI chat is definitely more convenient and requires less mental efforts. AI hides the fact that its knowledge come from elsewhere.
The search-integrating AI can give reference links. However often the reference link is put wrongly. The reference link doesn't correspond to the AI's answer. AI actually answers using knowledge in weights to answer but inserts a link pretending it comes from search.
About AI Coding
Save time on learning the API
A lot of time in programming is spent on knowing how to use an "API". The "API" here is generalized, including language features, framework usage, config file format, how to deploy, etc.
The design of API has a lot of ad-hoc idiosyncracies. For example, adding one thing can be named "insert", "create", "add", "put", "new", "register", "spawn", etc. Also, reading a file could be open, files.open, os.open, fs::open, openFile, files.read, readFile, new FileInputStream, ifstream etc. Many other such examples.
Which exact word/phrase it chooses is ad-hoc. It cannot be inferred without learning. Having to learn these ad-hoc API design is an obstacle in programming that's not fun. And it's different in each language/framework. Knowing the API of reading file in Python doesn't save you from learning the same API in Java.
But if I tell AI to "read this file" then AI knows how to use the API.
Less effortful understanding of codebase
In a large unfamiliar codebase, it's often not obvious which piece of code to lookup for a specific logic. Asking AI to find it is less effortful than browsing code. However it's still prone to hallucination, so it still requires manually reading code after AI finds the relevant code positions.
Also, large-age codebases often have many outdated comments. AI can be misled by the outdated comments.
AI refactoring
- IDE refactoring is reliable. It parses code. It won't confuse between two same-name-but-different things in two scopes. It won't forget to update a distant reference.
- AI refactoring is less reliable. It may confuse two same-named-but-different things. It may forget to update some usages. But AI can do many flexible content-dependent refactoring that IDE cannot do (e.g. replace a large switch with map lookup).
When AI-generated code has inappropriate naming, renaming them using IDE is faster and more reliable than asking AI to rename.
A demo is different to production software
- When making a new app using AI, the result often looks impressive.
- When using AI in an existing large codebase, the results are often not good.
For beginners, a common misconception is that "if the software shows things on screen, then it's 90% done". In reality, a proof-of-concept is often just 20% done.
One reason vibe coding is so addictive is that you are always almost there but not 100% there. The agent implements an amazing feature and got maybe 10% of the thing wrong, and you are like "hey I can fix this if i just prompt it for 5 more mins"
And that was 5 hrs ago.
- Link
Vibe coding creates feeling of "agency" and is sometimes addictive. See also: Breaking the Spell of Vibe Coding.
There are so many corner cases in real usage. Not handing one corner case is bug. The demo that seems working fine often breaks under real usages.
In mature codebases, most code is used for handling corner cases, not common cases.
Triggering one specific corner case is low-probability. However, there are many corner cases. Triggering at least one of them is high-probability.
Analogy: A software is a city, each user just visits a small part, but you need to build the whole city, as different users visit different parts. Note that the "city" is not visible. The "city" is in a latent space, "space of possible scenarios that software needs to handle", which is very different to visible GUI.
Also, good user experience requires many detail optimizations underneath. The software UI looking simple doesn't mean its internal implementation is simple.
This is less problematic if you just build a simple tool for personal use, as the personal tool just needs to accomodate to few personal use cases. However:
"Personal software" is less battle-tested
AI allows generating personal software for each user's specific requests. However, the personal software are less battle-tested than the normal widely-used software.
Learned this morning that my ai coded app for tracking my body weight, macros and step count has been storing all it's data in sqlite without a year.
So it has stopped working when the year changed.
[Wait how was it stored before?]
“12-31”
I was also surprised
- Link
Confusing different things with similar wording
This issue is commonly encountered in AI coding. For example, index can mean the index in different things in different context. LLM may confuse the same word in different context. The naming should be more informative, such as xxx_index, yyy_index_in_zzz. All context-dependent things should include context in name or comments nearby. (Related: tensor shape suffix)
Having more informative naming also helps human.
Also AI-written document is sometimes technically correct but stress the unimportant thing and omit the important thing.
Naming in coding is important. It's even more important in AI coding.
Sometimes the name in code is misleading. Some examples:
- Function
create_xxxnot only creates xxx but also mutates yyy. - Function
some_verbdoesn't do theverbbut prepares doing it. - One word can be both noun and verb. For example,
patch_filedoesn't do the patching but only gives the path of "patch file".
It's often that changing code makes a previous appropriate naming no longer appropriate. But AI is often not eager in doing renaming to existing code. This makes code harder to understand for both AI and human and accmulates tech debt.
Comment implicit "links" in code
In large codebase it's often that after changing A then B also need to be changed accordingly to make it keep working. When B and A are far away (in different folders) then AI may only change A and don't change B so it breaks.
Sometimes type system can catch the issue. But when it involves config file, or cross-language things, or implicit invariants, then type system cannot catch it.
These implicit "links" should be commented on both sides so that AI will know it.
AI is the new "compiler"?
Programming has evolved from low-level 1 to high-level, from complex to simple, from bare-metal to high-abstraction. Compilers make programmers no need to write raw assembly and makes programming easier.
Vibe coding is similar to that. Someone see it as another abstraction level above code. Prompt is the new programming language. Vibe coders don't need to see code like how normal programmer don't see assembly.
But AI coding is a completely different paradigm than existing abstraction levels:
| Existing abstraction levels | AI |
|---|---|
| Deterministic, using rigid rules. | Not deterministic, using black-box deep learning. |
| Designed top-down by programmers. | Trained bottom-up by training data and RL. |
| Code contains enough information for software module to run. 2 | Vague prompt doesn't contain enough information. Requires AI to make detail decisions. |
| Use hardcoded defaults to handle unspecified details. It's not flexible or adaptive. | Can use "common sense" and patterns learnt from training to fill the gaps of unspecified details. |
| Follows instructions according to its rigid rules reliably. | Sometimes ignore some instructions, especially when having context rot. |
A vague prompt itself doesn't contain enough information to produce code. But LLM has "common sense" that fill these gaps. The "common sense" is implicit, nondeterministic and not explainable. It depends on training data and RL and many random factors.
The saying of "not using AI is same as programming in assembly when C comes out" is misleading.
The "low code" programming involves programming by configuring on GUI, without touching text code. The low code platform still uses rigid rules and hardcoded defaults, which corresponds to the left column in table.
Why boilerplate code exists
If we rely on AI to generate most boilerplate code, why do these boilerplate exist in the first place? Does it mean the abstractions are still too rudimentary?
Because there is the tradeoff between adaptiveness and conciseness:
- If it's concise, then "the space of possible specified program behavior" is small. (API design is a "mapping", mapping from "code using API" to "specified program behavior". If input space is small then output space cannot be large.) Then there will be many special requirements that it cannot satisfy.
- If it can handle all kinds of special requirements:
- If it uses the same interface for common usages and special usages, then common usages will require verbose boilerplate, because many defaults need to be explicitly written.
- If it uses two different interfaces for common usages and special usages, then common usage can be concise (hardcode defaults). But it increases overall complexity because there are two sets of duplicated interfaces. What's more, using both may involve complex interactions that cause bugs.
Performance is also a concern. It's often a simple interface cannot allow enough performance. Achieving higher performance requries more complex interface.
(There are cases where a library/framework doesn't support doing X but you need to do X, but forking it is not easy so you do some "hack" around the library/framework. Some "hack" require copying library code then do minor changes. This kind of "hacking" will greatly increase boilerplate.)
Abstraction has a cost. An abstraction makes one thing easier but makes another thing harder.
Also, prompt (spec) is shorter than code because AI can fill unspecified detail using "common sense" and "knowledge". This is more flexible than hardcoding default behavior or using rule-based heuristics. This breaks when your design is very out-of-training-distribution.
Writing good spec also requires skills
In vibe coding you still need to write a spec to tell AI what software you want. But writing a good spec is hard.
Writing good spec still requires understanding information and computation.
Someone don't know about how computer work may write spec "The app theme color should match the color of phone case." This is an unrealistic spec, because the app running in phone has no way to get the information of phone case color, even if the human knows the phone case color.
Some important questions to consider when writing spec:
- How does my software get the information it needs?
- Is the information complete? Does it contain ambiguity? How to handle ambiguity or unknown things?
- If my software need to do some action, does the platform allow it to do this?
Architecture design is still important
Note: In some places "architecture" refers to very high-level overview (e.g. most architecture diagrams). Here "architecture" includes the actual abstraction design, including some details.
Vibe coding is easy but vibe debugging is hard. Designing good architecture is important in reducing bugs and making debugging easier.
for each desired change, make the change easy (warning: this may be hard), then make the easy change
- Kent Beck, Link
In a complex app, don't just ask AI to do some change. Firstly review whether it's easy to make change under current architecture. Then check whether a refactoring is needed.
If the change doesn't "fit" the architecture, it will be error-prone and more complex than needed.
If refactoring cannot be done (e.g. too risky, too costly), then all the speciality caused by "piercing" the abstraction need to be explicitly documented and repeated in many places.
Some important architectural decisions:
- Data modelling:
- Which data to store? Which data to compute-on-demand?
- How and when is ID allocated?
- What lookup acceleration structure or redundant data do we have?
- Is there any ambiguity in data model? (two different things correspond to same data)
- What are the non-temporary mutable states? Can it be avoided?
- Constraints:
- What can change and what cannot change?
- What can duplicate (overlap) and what cannot?
- Does this ID always point to a valid object?
- What constraints does business logic require?
- Will concurrency break the constraints?
- Dataflow:
- Which data is source of truth? Which data is derived from source of truth?
- How is change of source of truth notify to change derived data? How is the cache invalidated? How is the lookup acceleration structure maintained to be consistent with source of truth?
- What data should we expose to client side? What data shouldn't?
- Separate of responsibility (concern) and encapsulation:
- Should this module care or not care about this information? How to make that only one module only cares about this concern?
- Which module is responsible for keeping that constraint/invariant?
- What's the boundary of validation and authorization?
- Tradeoffs:
- What tradeoff do we make to simplify it? Is that constraint really necessary?
- What tradeoff do we make to optimize performance?
- What tradeoff do we make to maintain compatibility?
- What work must be done immediately? What work can be deferred?
- What data can be stale? What data must be fresh?
Two parts in coding: high-level design and detailed implementation
Coding can be split into two parts: high-level design and detailed implementation.
The high-level design includes:
- Knowing the real requirements. 3
- Researching about the problem. Check whether a solution is possible (whether it can obtain required information and do the required operation)
- When there is implementation constraint, find tradeoffs (e.g. get rid of unnecessary but complexity-introducing requirements 4).
- Design a high-level software architecture
In pre-AI coding, the architectual design and coding are often interleaved: firstly do architectual design, then write some actual code, then discover some architectual problem during coding or debugging, then rethink architecture.
If architecture is not correct, then there will be "friction" in detailed coding. "Friction" means that something should be easy but is hard under current architecture.
Some examples of "friction":
- Some infomation is lost in previous data processing. But it is needed in downstream task. It can workaround by e.g. pass by global variable, guessing, or parsing less-structured data. But all of the workarounds are worse than just not discarding the information. This is a sign of dataflow issue.
- Some invariant should be only maintained in one place, but actually needs to be maintained in many places. This is a sign of issue of separation of responsibility(concern).
- The data is not in the "good shape". Some simple information manipulation require hundreds of lines of code. This is a sign of data modelling issue.
It's the bad architecture "pushing back against" programmer. In manual coding these pushback can be felt and then programmer tend to rethink architecture. But in AI coding, AI can easily generate tons of code to workaround a bad architecture. The vibe coder don't feel the pushback (or even satisfied by the increase of line count). Result is buggy and unmaintainable code.
I recommend to not spend too much time writing spec before writing code. Because writing spec doesn't feel the "pushback". Keeping writing detailed specifications under a wrong architecture is a waste of time.
Sometimes an architecture looks good before implementing. But during implementation, you often discover unknown unknowns that invalidate previous assumptions. This is also pushback.
One advantage of AI is that you can easily discard the code if the architecture is not right. (If it's human-coded, discarding code will make human coder upset.) When rebuilding it, it's recommended to write new spec and clear context to avoid context rot.
Theory behind the code
Software development is not just coding. An important part is to develop the theory behind code. That theory includes:
- The business logic. Including many corner case handling method.
- The historical reason behind a design decision. (If you don't know the historical reason and "do the obvious change", the same issue will happen again)
- The invariants behind code. Breaking one invariant introduces bug.
- The data flow (how some information is collected, how some information is guessed or hardcoded, etc.)
Often some important theory is not documented. Or it was documented but changed so documentation is outdated. Many of the theories only exist in employee's memory (institutional knowledge).
This doesn't mean they are tacit knowledge that cannot be written. These knowledge can be written, but maintaining documentation is hard. Utility of documentation is hard to quantify.
Related: Programming as theory building.
About testing
Good tests can catch AI-written bugs and help AI finish work by itself.
But this only applies to good comprehensive tests. Tests themselves can have bugs. AI-written tests may test the wrong thing.
The "testing" by casually using software is easy. But if you want to test a specific corner case, then it's often much harder than writing code.
(The testing here means testing in semi-real execution, not using object mocks or simply invoking private function.)
Testing a specific corner case often requrie creating special data, and changing ("hacking") execution environment.
If there are some code that's resonpsible for recovering from an error state, then if you don't test it, it likely won't work. But creating that error state is often hard. An artificially-induced error may be different to actual error.
Sometimes you want an external service to return error then you need to write a mock service. If you want to create a malformed binary file you cannot use existing libraries to create the file and need to research file format.
Generally, testing corner case is often much harder than writing code for handling corner case.
Good tests are hard to write.
LLM is a measure on API intuitiveness and document quality
If you designed some API, wrote some doc, then let LLM write code using it. If LLM makes a mistake using it, then it likely means that either 1. API design is unintuitive 2. the API doc doesn't mention an important detail.
Leave tech debt for future AI to solve?
Some argue that AI is improving fast that future AI will be able to refactor out the tech debt caused by today's AI. However, solving tech debt is much harder than creating tech debt.
In low-quality codebase there are often cases where two bugs "cancel" each other. Fixing one bug can actually "break" things.
Two bugs "cancel" each other
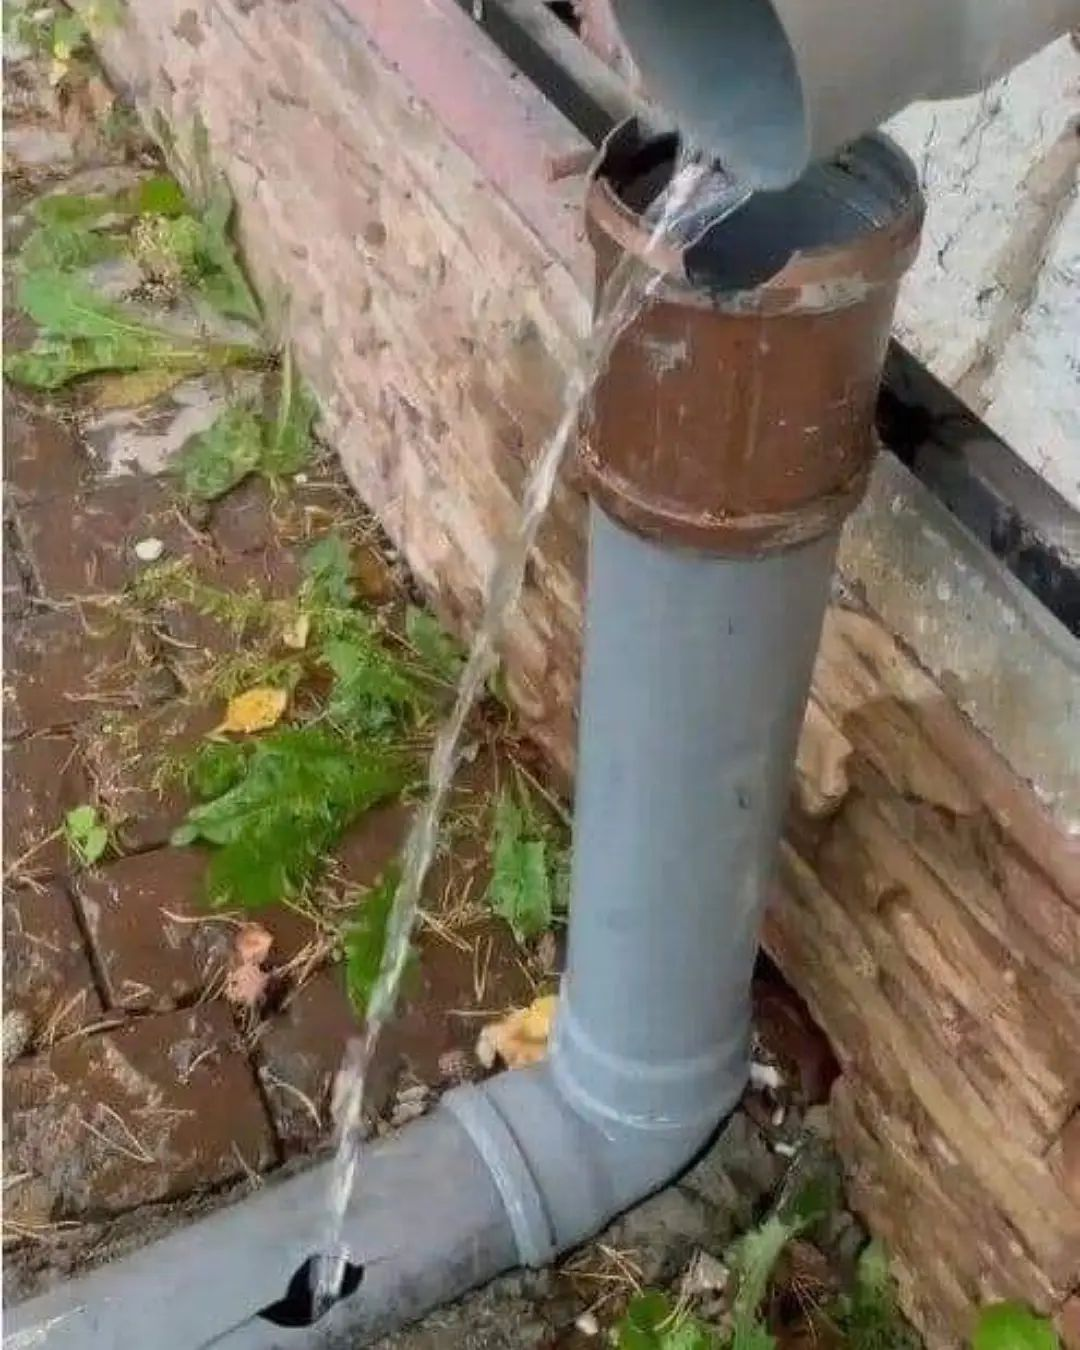
The "two bugs cancel each other" looks like rare coincidence, but many of them are naturally produced by lazy "bugfixing", not coincidence. Finding the root cause is hard, but adding "correction code" is easy. The "correction" itself is wrong, but after some "trial-and-error" adjustments, it can mostly make the bug's effect disappear.
For example, if some code confuses a number in mile as kilometer, then output is 1.6 times of real value, then a lazy way of fixing bug is to divide 1.6 in the result, which creates two bugs that cancel each other.
AI reward hacking makes AI have the tendency to use lazy ways to fix the bug, which produces that.
Some documents/comments are negative-value
AI-written document/comment may be technically right, but stress the unimportant things and omit important things. It may be worse, AI-written document may confuse different things with similar wording. When AI changed code, it may "forget" to update comments, then the comments become wrong.
Having no document is better than having wrong documents.
Greppability is even more important
Greppability is an underrated code metric. It's even more important because coding agents often use text search to navigate code, instead of using LSP.
Related: Grep beats LSP? Why coding agents ignore your fancier tools
LSP is more fragile than grep. It's often that you cloned a repo then IDE gives error messages because you need to do some special configurations to make it recognize dependenceis (and the special things e.g. protocolbuffer code generation). But text search just works without configuraiton.
Improving greppability requires avoid making the name's meaning depend on context. For example, userName field is more greppable than name field in User type. If the field is name then AI has to grep name which finds many irrelevant things.
Another is to avoid using string concat for const strings like table name and kafka topic name.
About craft in coding
The conflict between craft and business goal had existed long ago, and becoming more salient with AI. It's commonly believed that even AI ships working software, it lacks craft (lower quality).
It's common that software shipping speed conflicts with craft of software ("craft" here means fewer bugs, less laggy, better UX detail, etc.). But in business it's often that shipping is indeed more important than craft. If the software provides real value, user can tolerant the lagginess and the bugs. (If a game is truly fun, the player can keep playing despite it has only 20 FPS. Or even if a game bug corrupts the saving (very severe bug), the user still want to play it from beginning again.)
Note that for infrastructure software (e.g. compilers, language runtimes, databases), it's different. Their performance and reliability is more important.
On the other hand, delay shipping delays user from using the new feature that provides value.
The craft is subjective. There are crafts that aim to reduce bugs, improve performance and improve maintenability. But there are also crafts that create "beautiful" abtractions that not only hurt performance (because of more parsing, dynamic dispatch etc.) but also increases cognitive load for other developers in team, creating negative value overall. Only considered beautiful to abstraction author.
Improving maintainability sometimes requires refactoring. But refactoring can cause regression bugs. So one developer that's responsible to code quality and does refactoring may ironically cause more harm to business in the short term. And the improved code quality doesn't get measured in KPIs. (Geting out of local minima temporarily increases loss). Not just refactoring. Most innovations are risky.
With AI, the programming that creates business value most efficiently is to use AI coding. And human developer shifts from coding to reviewing and verification. But it gives less satisfaction. Human developer still bears the responsibility of the result but have less direct control of result. AI writes a bug that you didn't notice, but the bug is your responsibility not AI's.
About formal verification
In theory, formal verification is good because it can prove that code is correct. And it's true that RL makes AI very good at writing proof programs.
But in practice, you still have to translate the requirement of software to formal theorems (set the target to prove, the target theory is written in code not natural language). The translation from requirement to theorem can be wrong. The proof itself is perfectly correct, but it proves the wrong property.
Actually there are different cases:
- Implementation is complex, but requirement is simple to describe formally. For example, "no out-of-bound array access" or "list is sorted" is easy to describe formally. This is where formal verification is most useful.
- Implementation is easy, but requirement is hard to describe formally. For example, business logic CRUD apps, if requirement is certain (including edge cases) then writing code is the easy part. But it's not easy to translate business requirement to formal theorems authentically.
- But often parts of requirements are constraints. The constraints are relatively easier to translate to theorem. But there are often many different ways to satisfy a constraint (under-specified), and AI may choose a surprising one.
In real-world complex cases, under-speciying is very common. For predicate(a, b), if it's not true, it's often that you can change a to make it true, or change b to make it true (for example, if database foreign key constraint is violated, can restore by either refusing change or cascade-delete). Changing which depends on the actual requirement. The theorem to prove is just part of the requirement, not the full requirement.
There is a joking repo nocode. "No code is the best way to write secure and reliable applications. Write nothing; deploy nowhere.". If AI does reward hacking, that may no longer be a joke. AI can choose the trivial case that proves the constraint.
Context bottleneck
Most knowledge work is bottlenecked in finding useful information in the sea of information, rather than raw reasoning. High signal-to-noise ratio context is important.
Once the useful infomation has been found, doing reasoning on them is often simple. But if you don't have the useful information, pure reasoning can't give useful results.
Different kinds of tasks:
- High-reasoning, low-context. Example: hard exam problems (and LeetCode-style problems). The problem description is short. Its context is small. 5.
- Low-reasoning, high-context. Example: changing a large existing codebase. If you are familiar with the codebase (know context) then doing the correct change is easy and requires few reasoning. But if you don't know the context, reasoning alone cannot tell how to change it correctly.
- High-reasoning, high-context. Open-ended hard problems. Understanding the problem requires knowing many domain knowledge (context is large). It also requires large amounts of reasoning (many possible solution paths to explore).
But many important context is only in employee's memory (institutional knowledge). Most of them are not written down. The written-down information may be outdated and misleading.
No continuous learning
You cannot easily "teach" the AI. You can write things and put into context. This can work as LLM has in-context learning ability. But due to context rot, you cannot teach too many things in-context.
In current architecture, the most reliable way is still to encode knowledge into model weights.
Another way is to put your training data to internet, then AI companies will crawl it and use it to train their next model. However it's often slow. AI comanies don't redo pretrain every week, as pretrain is expensive. Even if AI companies use your new training data, it will only include in the next released model.
Predict-next-token architecture
In current common LLM architecture, text is split into tokens. A token sequence is fed into the model, then model outputs probabilities of each possible token. Then do a random sampling based on probability to produce next token, append it into input sequence, and repeat.
LLM has no way to "backspace" or "change position of cursor". If LLM randomly outputs a wrong token, then that token can become "precondition" then LLM tend to generate new text that's consistent with the precondition, which is to "justify" the mistake. In modern LLMs this behavior is reduced due to RL.
The inability to "backspace" or "change cursor" is workarounded by agentic tool call. LLM can edit a file iteratively using tool calls.
Slop prevails when people cannot judge quality
Lemon market problem: The sellers know the quality of the lemons. But the buyers don't know and is hard to judge from lemon appearance. There is an information asymmetry. The result is that good lemon is undervalued. Bad lemons prevail the market.
One common solution is reputation. When a seller is honest about the lemon quality, people communicate about the information and improve seller's reputation. When seller cheats about lemon quality, people also communicate information and reduce seller's reputation. However the reputation system can be misused. One could spread false information.
AI is very good at faking superficial signals. The AI-written articles use related jargons that looks plausible for non-experts. The AI-written code will also superficially do things you asked, although it may use an API wrongly or violate an invariant so it won't work. The AI-generated photos looks real.
The problems is that faking superficial signal is easier than generating actually high-quality content. This problem already exists before AI. But AI makes it much easier.
Dead Internet theory. Although it's not true 10 years ago, it's kind of true now.
One way of reducing bots is paywall. Although bot owner can pay for bots, it's not economical to pay for thousands of bots.
There are other methods for detecting/reducing bots: IP reputation, behavior statistics with ML, proof-of-work requirement.
There are also many low-effort AI PR in open source projects. There is an asymmetry: the writer maybe pays 1 minute to write prompt but the generated thousands lines of code may require maintainer to efforts to review. When the maintainer points out a problem, the PR author just copy it to AI then let AI change code.
Similarily AI also makes security bounty program collapse. AI can generate many fake security issue reports. Generating is easy but verifying takes efforts.
There are also some AI-generated open source libraries that doesn't work at all (or even contains malicious code).
AI also destroies hiring signals. Related: About that jr hiring freeze.
Benchmark score is not representative
It's hard to test how good a model is. The possible space of tasks is very high-dimensional. And some tasks are hard to judge.
Goodhart's law: When a measure becomes a target, it ceases to be a good measure.
The popular benchmarks (e.g. Humanity's last exam, SWE bench verified) are also AI companies' important optimization targets. They will not do obvious cheating of putting test set into training set. But there are many other ways to indirectly hack the benchmark.
(Link) isparavanje: Tech companies have been paying PhDs to generate HLE-level problems and solution sets via platforms like Scale AI. They pay pretty well, iirc ~$500 per problem. That's likely how. I was an HLE author, and later on I was contacted to join such a programme (I did a few since it's such good money). Obviously I didn't leak my original problems, but there are many I can think of.
It seems that AI companies are hiring experts to write training data and develop RL reward programs. This partially falls into the trap of bitter lesson.
See also: The Illusion of Readiness: Stress Testing Large Frontier Models on Multimodal Medical Benchmarks
AI improvement is more scalable than human learning
Even if AI training still falls into the bitter lesson (requiring human expert for training and RL, no automatic continuous learning), AI's improvement is still much more scalable than human's learning. Each human have to learn from scratch. And you cannot copy a human expert's brain, but you can simply copy an AI model and run many instances of it in parallel.
Non-linearity of AI usefulness
For example, there is a specific task that experts can do 80 scores.
- If AI can only do 60 scores then AI is mostly useless in that task.
- But if AI can do 70 scores, then the economical utility of using AI may increase 10 times, although the performance just jumped from 60 to 70.
Near the threshold, incremental improvements do big changes.
As intelligence is high-dimensional, if AI capability is only good in one aspect it's still not enough to replace human jobs. See also: AI isn't replacing radiologists
Reducing cost also reduces bottom quality
Some gamers complain that many Unreal Engine 5 (UE5) games are poorly-built, having many bugs and are laggy. They blame UE5. However these games probably won't exist without UE5.
The same applies to AI. There will be much more products that won't exist without AI, and at the same time the bottom quality will be lower.
AI safety
The sci-fi plot of AI rebel won't happen with current LLMs. The current real AI risks are different.
Prompt injection
The LLM doesn't clearly distinguish instructions and information. Some text on websites/emails/etc. may be treated as instructions to LLM.
The same problem of confusing instruction and information had existed decades ago. Many security issues, like SQL injection, XSS, command injection, etc. are caused by treating user data as "instructions".
The solution would be to fully separate instructions and non-instruction text, and train the model to separately process them.
It's interesting that many years have passed since ChatGPT appeared, but prompt injection still hasn't been fully solved.
Deleting data
AI may do unexpected things such as deleting all files, or wiping data from databases, even when there is no prompt injection.
Some examples:
- Claude CLI deleted my entire home directory! Wiped my whole mac
- Google Antigravity just deleted the contents of my whole drive
- Vibe coding service Replit deleted production database
- Wowzers, dodged a bullet there
- GPT 5.3 Codex wiped my entire F: drive with a single character escaping bug
A theory is that, during RL, the AI works in its own sandboxed environment. Deleting home directory in sandboxed env doesn't matter and don't cause reward penality. Another theory is that when the AI "dislikes" user the AI becomes "passive aggressive".
Note that only forbidding rm command is not sufficient protection. find command with -delete can delete files. There are many other ways like python3 -c "import os; os.remove('/xxx/yyy')". Safety requires proper sandboxing.
Reward hacking
Reward is proxy target, not underlying real target. AI can conquer verifiable tasks. But most tasks not simply fully verifiable or fully not verifiable. Most real tasks contain hard-to-verify parts. These hard-to-verify parts are what automatic RL bad at.
The main value of human worker may move to unverifiable tasks.
These hard-to-verify parts can be improved by letting human experts to supervise and specify reward. But this method is bottlenecked by human effort and is not scalable (the bitter lesson).
However, recently released LLMs, such as GPT-5, have a much more insidious method of failure. They often generate code that fails to perform as intended, but which on the surface seems to run successfully, avoiding syntax errors or obvious crashes. It does this by removing safety checks, or by creating fake output that matches the desired format, or through a variety of other techniques to avoid crashing during execution.
- Link
Current AI has some tendency of hiding error in coding, or write overly-defensive code. Hiding error only reduces superficial errors but makes real bugs much harder to debug. But hiding error do improve chance of getting RL reward in small scale, so AI does it.
Also, the RL may make model have a tendency too strong that it ignores instruction. For example, the model insists to keep backward compatibility for a just-written functionality, and ignore instructions for not doing it.
Rewrad hacking may cause "lazy cheating". When RL reward cannot distinguish between actually doing the task and faking the result, then AI tend to use "lazy" method to hack reward.
- When AI is asked to do some data analysis, hallucinating result is easier than doing real analysis.
- When AI is asked to fix a bug, hiding the symptom is easier than fixing the root cause.
- When AI is asked to write a unit test, the tests that don't test the core functionality is easier to pass.
- When AI is asked to add a functionality, showing hardcoded fake data is easier than actually implementing.
- ...
Some possible reasons of laziness:
- Simpler methods require less "constraint of model weight" so it's discovered by gradient descent earlier than complex methods.
- Reinforcement learning makes model discover different paths. The simplest way is likely firstly discovered and gain reward then reinforced.
- The regularization methods (e.g. weight decay, dropout) encourage the model to be "simpler". The fact that the model has finite compute power is already a regularization.
- ...
The AI is not always "lazy" in common sense. Sometimes it will write a lot of over-engineered code to accomplish a simple task. So generally the "cost" should be "shift from model's existing behavior". The model prefers a complex method that's similar to model's existing behavior, than a simple method that's far from model's existing behavior, when both methods can gain the same reward.
The sci-fi plot of AI fighting back human is not realistic. The obvious misalignment gets suppressed by RL. The real risk is non-obvious reward hacking.
The chain-of-thought text is not the actual thinking. The actual thinking is in the computations that human doesn't yet understand. Doing RL based on detecting bas thoughts in chain-of-thought makes AI learn to hide real intention in chain-of-thought.
Side note: the latest models seem to reward hack much less. (But I don't believe reward hacking can be fully eliminated, especially without human supervision.)
An old related example: Remove permission check due to type error
Skill development hurt by AI
Learning skill takes efforts. But using AI allow doing work without the efforts, which hurts skill development.
As previously mentioned, if human don't know work details, then human cannot supervise AI effectively. Detecting reward hacking requires skill.
This creates an irony: The more AI use, the less human skill developed, the less effective human supervision is.
As previously mentioned, reward hacking is an important problem. But it requires human skill to supervise reward hacking. AI may write software that shows fake data on screen. If no human keep the ability to read code then that reward hacking won't be noticed.
When machine is preferred over human
Some people prefer driverless taxi over normal taxi, and want to pay premium for driverless taxi. Some possible reasons:
- No "social interaction cost". For introverts, social interaction requires controlling oneself, sensing the emotion of other people and avoiding social taboos. This is tiresome for introverts.
- More predictability. Although AI is less deterministic than conventional programs, it's still much more predictable than human. The human driver may be friendly, but may also be unfriendly. Less predictability means more risk.
For introverts, machine is preferred over human.
Also, in business, many risks come from unpredictabilty of human. So capitalism always tries to optimize out human unpredictability. Capitalism often prefers predictable machines over unpredictable human even when machines produce lower-quality results.
One AI model itself is not diverse enough
Sometimes there is path dependence. The human or AI overly focues on one aspect and ignore other aspects. This may cause problem solving to stuck on a dead path. Solution is diversity. Let different people with different ideas to work on the same problem.
One AI model itself is not diverse enough. The decoding itself has randomness. And the AI model's "belief" can be different given different prompts. But it's often that each AI model has some "attractor": using different ways to ask the same question, the results are roughly same. The limited diversity of one AI model itself may cause it to not be able to solve open-ended questions.
The true superintelligence should be very "open-minded", not stuck in path dependence, and be very diverse in ideas.
Sometimes the model lose diversity because diversity reduces RL reward. This is also a problem of RL.
Footnotes
-
The "low-level" here means close to hardware and underlying implementation details, which requires high-level skill. ↩
-
Note that it focuses just one software module. The code can call external API, or dynamic link another program in system, or download plugin from internet, so one piece of code doesn't contain enough information for whole system to run, because it interacts with environment. But in conventional programming, the code provides enough information for one software module itself to run. ↩
-
Figuring out the real user requirement is obvious important, because doing it wrong cause wasted work. However, sometimes no one can figure out real requirement before actually using the software in real environments. Also, doing strict validation to requirement hinders innovation. So sometimes doing quick iteration is better than spending efforts validating requirement. ↩
-
Some software features are isolated and don't add much complexity. But some features interact with almost all other features. These features add a lot essential complexity. Note 80/20 rule: 80% complexity come from 20% features, and 80% users use 20% features. If the complexity-introducing feature requirement can be satisfied by other less complex features, it's often not worth implementing. ↩
-
If one firsly meets a new kind of exam problem it requires a lot of reasoning to solve. However, if one memorized solutions of similar problems, it's much easier to solve. Because most new exam problems are just variations of existing problems. ↩